
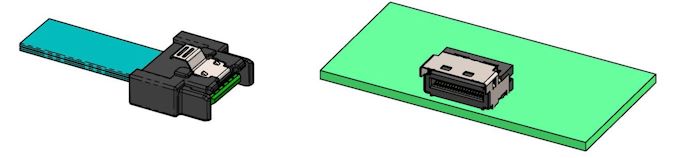
Following a relative lull in the desktop memory industry in the previous decade, the past few years have seen a flurry of new memory standards and form factors enter development. Joining the traditional DIMM/SO-DIMM form factors, we've seen the introduction of space-efficient DDR5 CAMM2s, their LPDDR5-based counterpart the LPCAMM2, and the high-clockspeed optimized CUDIMM. But JEDEC, the industry organization behind these efforts, is not done there. In a press release sent out at the start of the week, the group announced that it is working on standards for DDR5 Multiplexed Rank DIMMs (MRDIMM) for servers, as well as an updated LPCAMM standard to go with next-generation LPDDR6 memory.
Just last week Micron introduced the industry's first DDR5 MRDIMMs, which are timed to launch alongside Intel's Xeon 6 server platforms. But while Intel and its partners are moving full steam ahead on MRDIMMs, the MRDIMM specification has not been fully ratified by JEDEC itself. All told, it's not unusual to see Intel pushing the envelope here on new memory technologies (the company is big enough to bootstrap its own ecosystem). But as MRDIMMs are ultimately meant to be more than just a tool for Intel, a proper industry standard is still needed – even if that takes a bit longer.
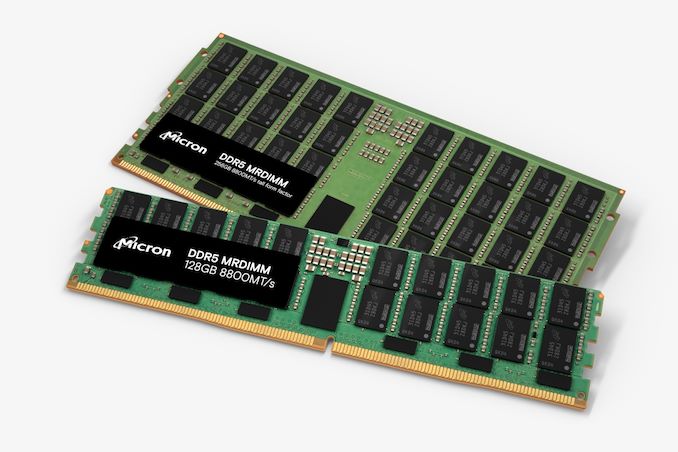
Under the hood, MRDIMMs continue to use DDR5 components, form-factor, pinout, SPD, power management ICs (PMICs), and thermal sensors. The major change with the technology is the introduction of multiplexing, which combines multiple data signals over a single channel. The MRDIMM standard also adds RCD/DB logic in a bid to boost performance, increase capacity of memory modules up to 256 GB (for now), shrink latencies, and reduce power consumption of high-end memory subsystems. And, perhaps key to MRDIMM adoption, the standard is being implemented as a backwards-compatible extension to traditional DDR5 RDIMMs, meaning that MRDIMM-capable servers can use either RDIMMs or MRDIMMs, depending on how the operator opts to configure the system.
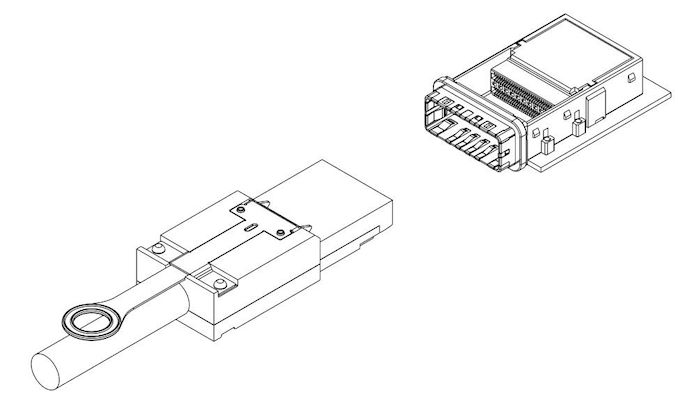
The MRDIMM standard aims to double the peak bandwidth to 12.8 Gbps, increasing pin speed and supporting more than two ranks. Additionally, a "Tall MRDIMM" form factor is in the works (and pictured above), which is designed to allow for higher capacity DIMMs by providing more area for laying down memory chips. Currently, ultra high capacity DIMMs require using expensive, multi-layer DRAM packages that use through-silicon vias (3DS packaging) to attach the individual DRAM dies; a Tall MRDIMM, on the other hand, can just use a larger number of commodity DRAM chips. Overall, the Tall MRDIMM form factor enables twice the number of DRAM single-die packages on the DIMM.
Meanwhile, this week's announcement from JEDEC offers the first significant insight into what to expect from LPDDR6 CAMMs. And despite LPDDR5 CAMMs having barely made it out the door, some significant shifts with LPDDR6 itself means that JEDEC will need to make some major changes to the CAMM standard to accommodate the newer memory type.
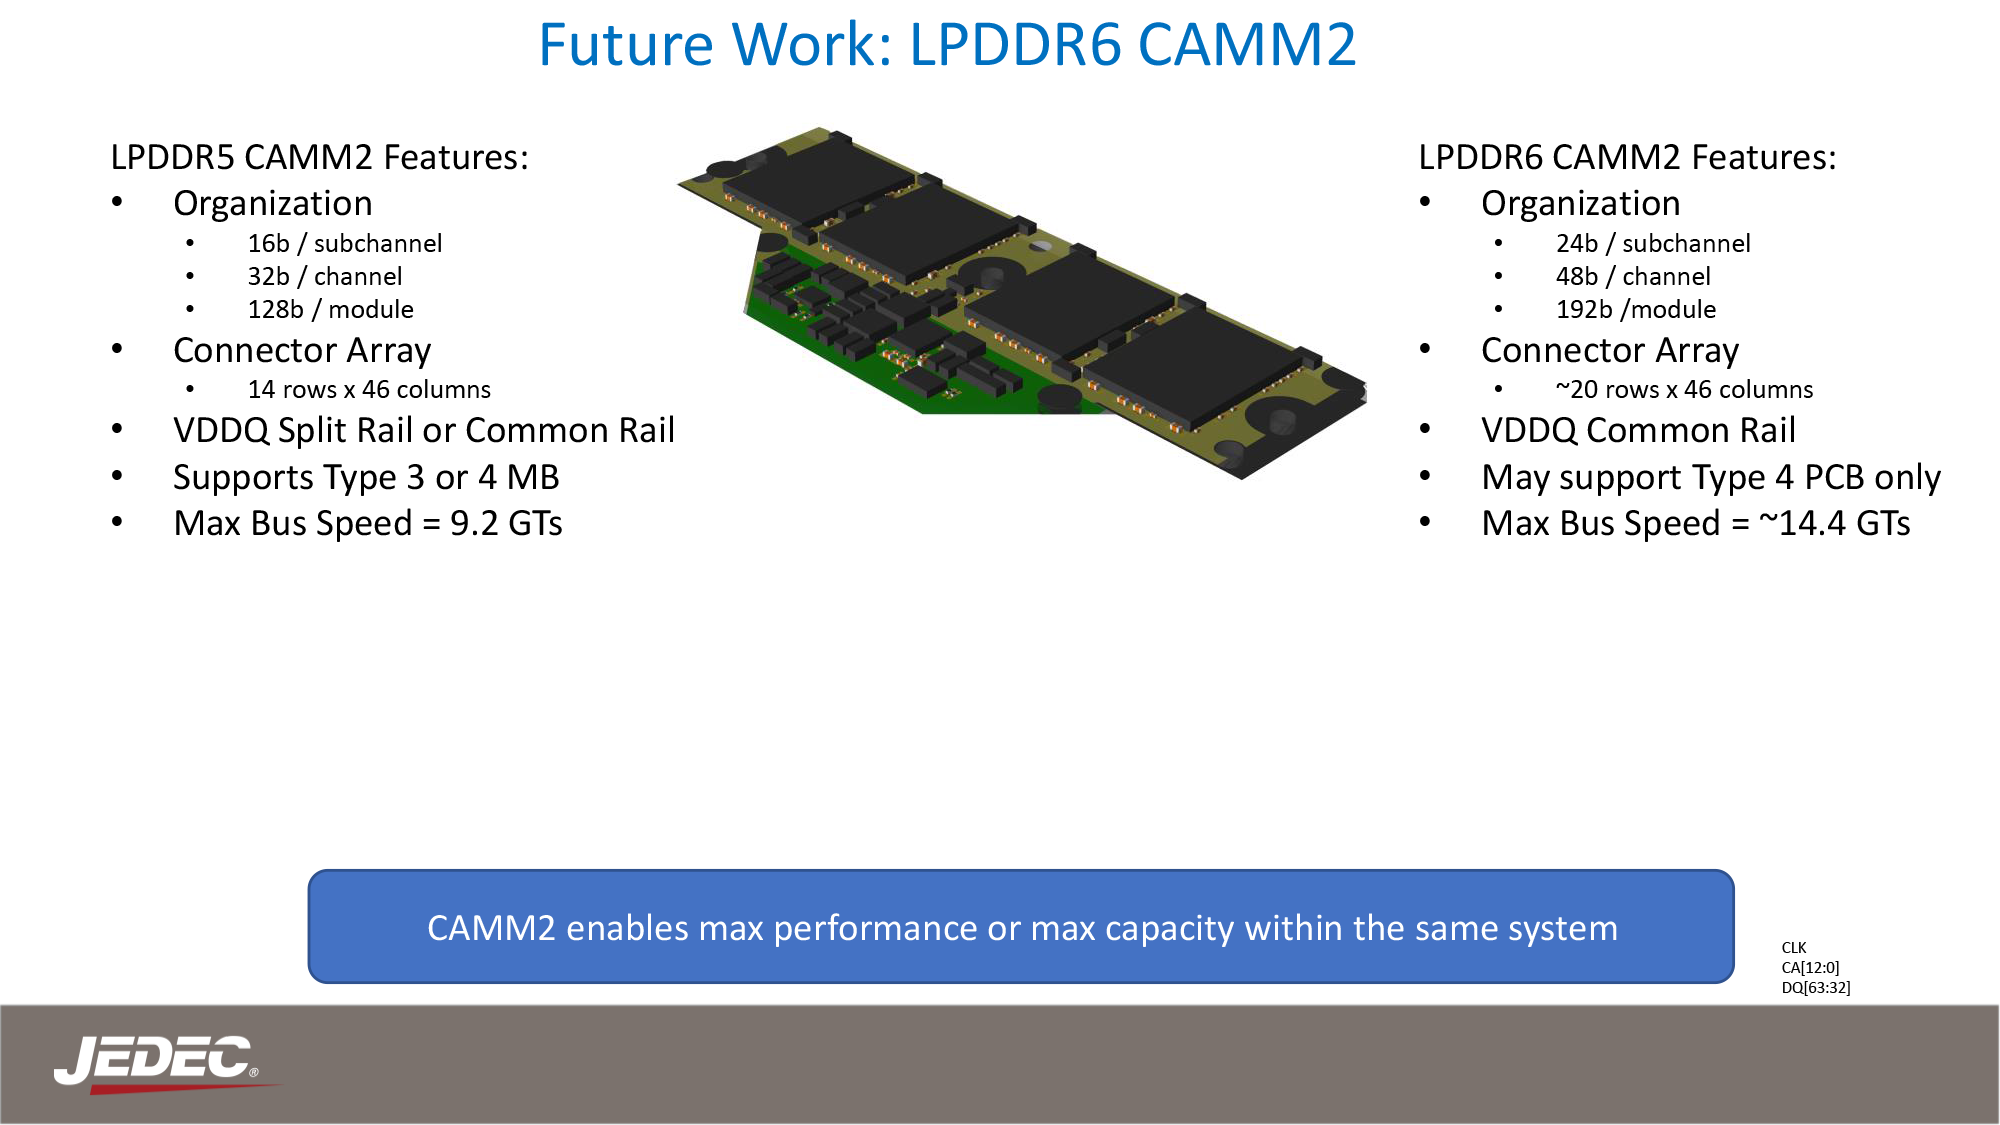
JEDEC Presentation: The CAMM2 Journey and Future Potential
Besides the higher memory clockspeeds allowed by LPDDR6 – JEDEC is targeting data transfer rates of 14.4 GT/s and higher – the new memory form-factor will also incorporate an altogether new connector array. This is to accommodate LPDDR6's wider memory bus, which sees the channel width of an individual memory chip grow from 16-bits wide to 24-bits wide. As a result, the current LPCAMM design, which is intended to match the PC standard of a cumulative 128-bit (16x8) design needs to be reconfigured to match LPDDR6's alterations.
Ultimately, JEDEC is targeting a 24-bit subhannel/48-bit channel design, which will result in a 192-bit wide LPCAMM. While the LPCAMM connector itself is set to grow from 14 rows of pins to possibly as high as 20. New memory technologies typically require new DIMMs to begin with, so it's important to clarify that this is not unexpected, but at th... Memory


In addition to revealing its roadmap and plans concerning its current leading-edge process technologies, TSMC also shared progress of its N2 node as part of its Symposiums 2024. The company's first 2nm-class fabrication node, and predominantly featuring gate-all-around transistors, according to TSMC N2 has almost achieved its target performance and yield goals, which places it on track to enter high-volume manufacturing in the second half of 2025.
TSMC states that 'N2 development is well on track and N2P is next.' In particular, gate-all-around nanosheet devices currently achieve over 90% of their expected performance, whereas yields of 256 Mb SRAM (32 MB) devices already exceeds 80%, depending on the batch. All of this for a node that is over a year away from mass production.
Meanwhile, average yield of a 256 Mb SRAM was around 70% as of March, 2024, up from around 35% in April, 2023. Device performance has also been improving with higher frequencies being achieved while keeping power consumption in check.
Chip designer interest towards TSMC's first 2nm-class gate-all-around nanosheet transistor-based technology is significant, too. The number of new tape-outs (NTOs) in the first year of N2 is over two-times higher than it was for N5. Though with that said, given TSMC's close working relationship with a handful of high-volume vendors – most notably Appe – NTOs can be a very misleading figure since the first year of a new node at TSMC is capacity constrained, and consequently the bulk of that capacity goes to TSMC's priority partners.
Meanwhile, there were considerably more N5 tapeouts in its second year (some where N5P, of course) and N2 promises to have 2.6X more NTOs in its second year. So the node indeed looks quite promising. In fact, based on TSMC's slides (which we're unfortunately not able to republish), N2 is more popular than N3 in terms of NTOs both in the first and the second years of existence.
When it comes to the second year of N2, in the second half of 2026 TSMC plans to roll out its N2P technology, which promises additional performance and power benefits. N2P is expected to improve frequency by 15% - 20%, reduce power consumption by 30% - 40%, and increase chip density by over 1.15 times compared to N3E, significant benefits to move to all-new GAA nanosheet transistors.
Finally, for those companies that need the best in performance, power, and density, TSMC is poised to offer their A16 process in 2026. That node will also bring in backside power delivery, which will add costs, but is expected to greatly improve performance efficiency and scaling.
Semiconductors
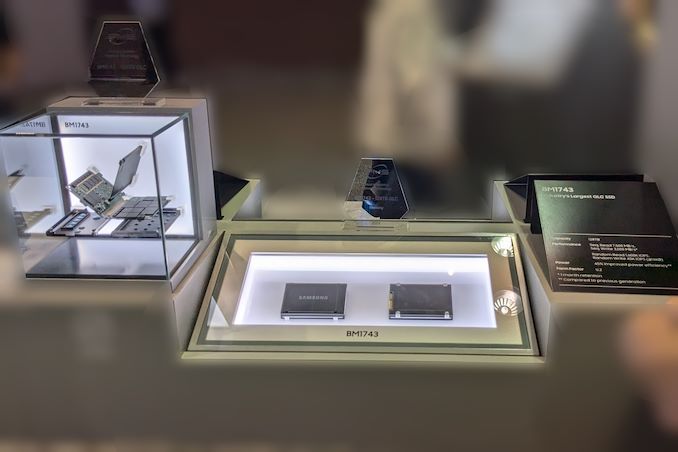
Samsung had quietly launched its BM1743 enterprise QLC SSD last month with a hefty 61.44 TB SKU. At FMS 2024, the company had the even larger 122.88 TB version of that SSD on display, alongside a few recorded benchmarking sessions. Compared to the previous generation, the BM1743 comes with a 4.1x improvement in I/O performance, improvement in data retention, and a 45% improvement in power efficiency for sequential writes.
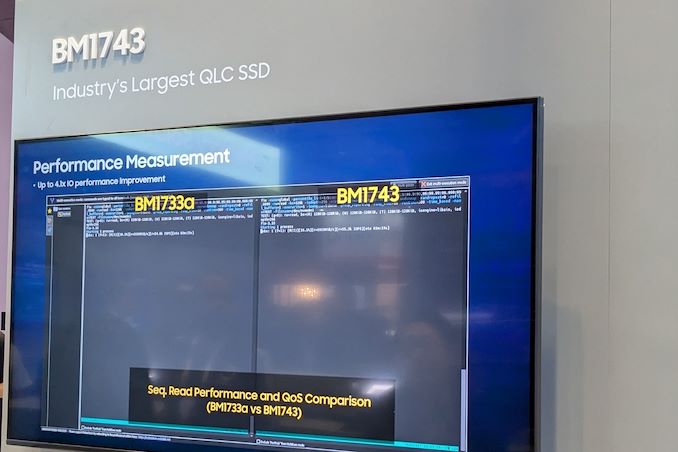
The 128 TB-class QLC SSD boasts of sequential read speeds of 7.5 GBps and write speeds of 3 GBps. Random reads come in at 1.6 M IOPS, while 16 KB random writes clock in at 45K IOPS. Based on the quoted random write access granularity, it appears that Samsung is using a 16 KB indirection unit (IU) to optimize flash management. This is similar to the strategy adopted by Solidigm with IUs larger than 4K in their high-capacity SSDs.
A recorded benchmark session on the company's PM9D3a 8-channel Gen 5 SSD was also on display.
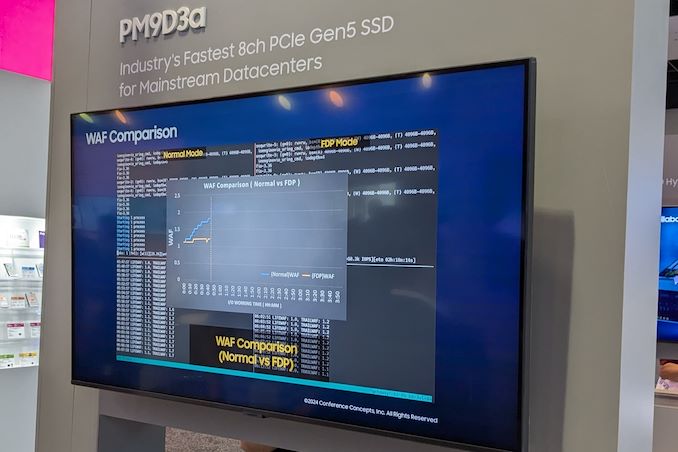
The SSD family is being promoted as a mainstream option for datacenters, and boasts of sequential reads up to 12 GBps and writes up to 6.8 GBps. Random reads clock in at 2 M IOPS, and random writes at 400 K IOPS.
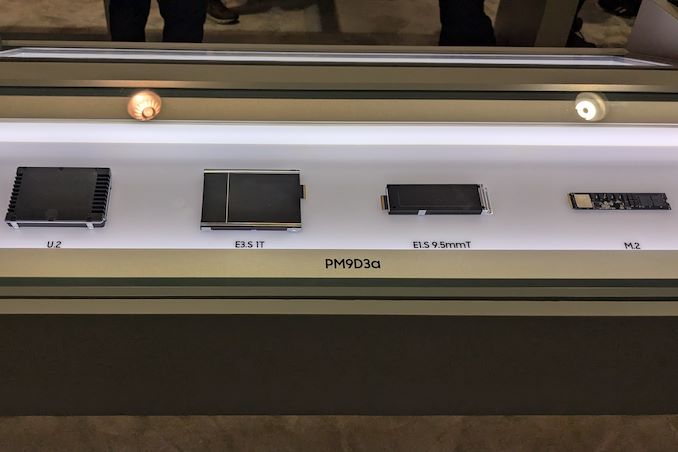
Available in multiple form-factors up to 32 TB (M.2 tops out at 2 TB), the drive's firmware includes optional support for flexible data placement (FDP) to help address the write amplification aspect.
The PM1753 is the current enterprise SSD flagship in Samsung's lineup. With support for 16 NAND channels and capacities up to 32 TB, this U.2 / E3.S SSD has advertised sequential read and write speeds of 14.8 GBps and 11 GBps respectively. Random reads and writes for 4 KB accesses are listed at 3.4 M and 600 K IOPS.
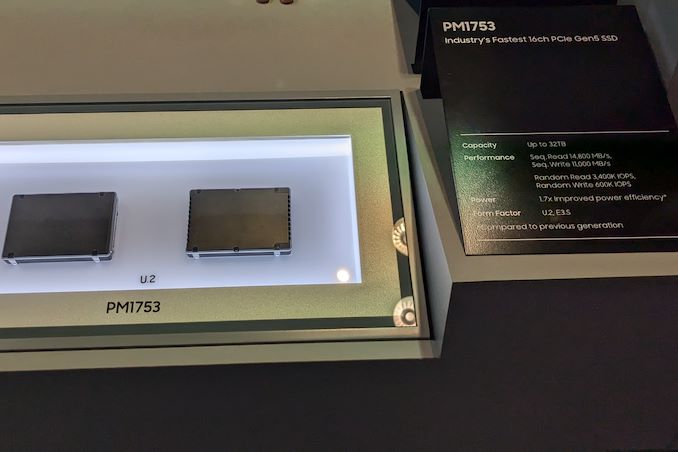
Samsung claims a 1.7x performance improvement and a 1.7x power efficiency improvement over the previous generation (PM1743), making this TLC SSD suitable for AI servers.
The 9th Gen. V-NAND wafer was also available for viewing, though photography was prohibited. Mass production of this flash memory began in April 2024.
Storage
In addition to revealing its roadmap and plans concerning its current leading-edge process technologies, TSMC also shared progress of its N2 node as part of its Symposiums 2024. The company's first 2nm-class fabrication node, and predominantly featuring gate-all-around transistors, according to TSMC N2 has almost achieved its target performance and yield goals, which places it on track to enter high-volume manufacturing in the second half of 2025.
TSMC states that 'N2 development is well on track and N2P is next.' In particular, gate-all-around nanosheet devices currently achieve over 90% of their expected performance, whereas yields of 256 Mb SRAM (32 MB) devices already exceeds 80%, depending on the batch. All of this for a node that is over a year away from mass production.
Meanwhile, average yield of a 256 Mb SRAM was around 70% as of March, 2024, up from around 35% in April, 2023. Device performance has also been improving with higher frequencies being achieved while keeping power consumption in check.
Chip designer interest towards TSMC's first 2nm-class gate-all-around nanosheet transistor-based technology is significant, too. The number of new tape-outs (NTOs) in the first year of N2 is over two-times higher than it was for N5. Though with that said, given TSMC's close working relationship with a handful of high-volume vendors – most notably Appe – NTOs can be a very misleading figure since the first year of a new node at TSMC is capacity constrained, and consequently the bulk of that capacity goes to TSMC's priority partners.
Meanwhile, there were considerably more N5 tapeouts in its second year (some where N5P, of course) and N2 promises to have 2.6X more NTOs in its second year. So the node indeed looks quite promising. In fact, based on TSMC's slides (which we're unfortunately not able to republish), N2 is more popular than N3 in terms of NTOs both in the first and the second years of existence.
When it comes to the second year of N2, in the second half of 2026 TSMC plans to roll out its N2P technology, which promises additional performance and power benefits. N2P is expected to improve frequency by 15% - 20%, reduce power consumption by 30% - 40%, and increase chip density by over 1.15 times compared to N3E, significant benefits to move to all-new GAA nanosheet transistors.
Finally, for those companies that need the best in performance, power, and density, TSMC is poised to offer their A16 process in 2026. That node will also bring in backside power delivery, which will add costs, but is expected to greatly improve performance efficiency and scaling.
Semiconductors
Samsung had quietly launched its BM1743 enterprise QLC SSD last month with a hefty 61.44 TB SKU. At FMS 2024, the company had the even larger 122.88 TB version of that SSD on display, alongside a few recorded benchmarking sessions. Compared to the previous generation, the BM1743 comes with a 4.1x improvement in I/O performance, improvement in data retention, and a 45% improvement in power efficiency for sequential writes.
The 128 TB-class QLC SSD boasts of sequential read speeds of 7.5 GBps and write speeds of 3 GBps. Random reads come in at 1.6 M IOPS, while 16 KB random writes clock in at 45K IOPS. Based on the quoted random write access granularity, it appears that Samsung is using a 16 KB indirection unit (IU) to optimize flash management. This is similar to the strategy adopted by Solidigm with IUs larger than 4K in their high-capacity SSDs.
A recorded benchmark session on the company's PM9D3a 8-channel Gen 5 SSD was also on display.
The SSD family is being promoted as a mainstream option for datacenters, and boasts of sequential reads up to 12 GBps and writes up to 6.8 GBps. Random reads clock in at 2 M IOPS, and random writes at 400 K IOPS.
Available in multiple form-factors up to 32 TB (M.2 tops out at 2 TB), the drive's firmware includes optional support for flexible data placement (FDP) to help address the write amplification aspect.
The PM1753 is the current enterprise SSD flagship in Samsung's lineup. With support for 16 NAND channels and capacities up to 32 TB, this U.2 / E3.S SSD has advertised sequential read and write speeds of 14.8 GBps and 11 GBps respectively. Random reads and writes for 4 KB accesses are listed at 3.4 M and 600 K IOPS.
Samsung claims a 1.7x performance improvement and a 1.7x power efficiency improvement over the previous generation (PM1743), making this TLC SSD suitable for AI servers.
The 9th Gen. V-NAND wafer was also available for viewing, though photography was prohibited. Mass production of this flash memory began in April 2024.
Storage
During the opening keynote delivered by AMD CEO Dr. Lisa Su at Computex 2024, AMD finally lifted the lid on their highly-anticipated Zen 5 microarchitecture. The backbone for the next couple of years of everything CPU at AMD, the company unveiled their plans to bring Zen 5 in the consumer market, announcing both their next-generation mobile and desktop products at the same time. With a tight schedule that will see both platforms launch within weeks of each other, today AMD is taking their first step with the launch of the Ryzen AI 300 series – codenamed Strix Point – their new Zen 5-powered mobile SoC.
The latest and greatest from AMD, the Strix Point brings significant architectural improvements across AMD's entire IP portfolio. Headlining the chip, of course, is the company's new Zen 5 CPU microarchitecture, which is taking multiple steps to improve on CPU performance without the benefits of big clockspeed gains. And reflecting the industry's current heavy emphasis on AI performance, Strix Point also includes the latest XDNA 2-based NPU, which boasts up to 50 TOPS of performance. Other improvements include an upgraded integrated graphics processor, with AMD moving to the RDNA 3.5 graphics architecture.
The architectural updates in Strix Point are also seeing AMD opt for a heterogenous CPU design from the very start, incorporating both performance and efficiency cores as a means of offering better overall performance in power-constrained devices. AMD first introduced their compact Zen cores in the middle of the Zen 4 generation, and while they made it into products such as AMD's small-die Phoenix 2 platform, this is the first time AMD's flagship mobile silicon has included them as well. And while this change is going to be transparent from a user perspective, under the hood it represents an important improvement in CPU design. As a result, all Ryzen AI 300 chips are going to include a mix of not only AMD's (mostly) full-fat Zen 5 CPU cores, but also their compact Zen 5c cores, boosting the chips' total CPU core counts and performance in multi-threaded situations.
For today's launch, the AMD Ryzen AI 300 series will consist of just three SKUs: the flagship Ryzen AI 9 HX 375, with 12 CPU cores, as well as the Ryzen AI 9 HX 370 and Ryzen 9 365, with 12 and 10 cores respectively. All three SoCs combine both the regular Zen 5 core with the more compact Zen 5c cores to make up the CPU cluster, and are paired with a powerful Raden 890M/880M GPU, and a XDNA 2-based NPU.
As the successor to the Zen 4-based Phoenix/Hawk Point, the AMD Ryzen AI 300 series is targeting a diverse and active notebook market that has become the largest segment of the PC industry overall. And it is telling that, for the first time in the Zen era, AMD is launching their mobile chips first – if only by days – rather than their typical desktop-first launch. It's both a reflection on how the PC industry has changed over the years, and how AMD has continued to iterate and improve upon its mobile chips; this is as close to mobile-first as the company has ever been.
Getting down to business, for our review of the Ryzen AI 300 series, we are taking a look at ASUS's Zenbook S 16 (2024), a 16-inch laptop that's equipped with AMD's Ryzen AI 9 HX 370. The sightly more modest Ryzen features four Zen 5 CPU cores and 8 Zen 5c CPU cores, as well as AMD's latest RDNA 3.5 Radeon 890M integrated graphics. Overall, the HX 370 has a configurable TDP of between 15 and 54 W, depending on the desired notebook configuration.
Fleshing out the rest of the Zenbook S 16, ASUS has equipped the laptop with a bevy of features and technologies fitting for a flagship Ryzen notebook. The centerpiece of the laptop is a Lumina OLED 16-inch display, with a resolution of up to 2880 x 1800 and a variable 120 Hz refresh rate. Meanwhile, inside the Zenbook S 16 is 32 GB of LPDDR5 memory and a 1 TB PCIe 4.0 NVMe SSD. And while this is a 16-inch class notebook, ASUS has still designed it with an emphasis on portability, leading to the Zenbook S 16 coming in at 1.1 cm thick, and weighting 1.5 kg. That petite design also means ASUS has configured the Ryzen AI 9 HX 370 chip inside rather conservatively: out of the box, the chip runs at a TDP of just 17 Watts.
CPUs
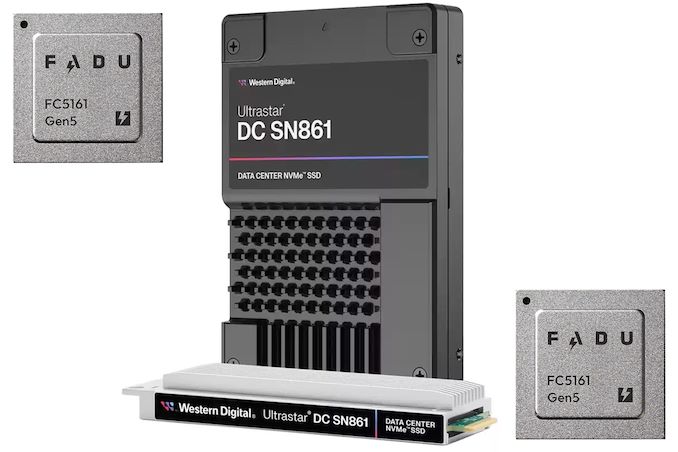
When Western Digital introduced its Ultrastar DC SN861 SSDs earlier this year, the company did not disclose which controller it used for these drives, which made many observers presume that WD was using an in-house controller. But a recent teardown of the drive shows that is not the case; instead, the company is using a controller from Fadu, a South Korean company founded in 2015 that specializes on enterprise-grade turnkey SSD solutions.
The Western Digital Ultrastar DC SN861 SSD is aimed at performance-hungry hyperscale datacenters and enterprise customers which are adopting PCIe Gen5 storage devices these days. And, as uncovered in photos from a recent Storage Review article, the drive is based on Fadu's FC5161 NVMe 2.0-compliant controller. The FC5161 utilizes 16 NAND channels supporting an ONFi 5.0 2400 MT/s interface, and features a combination of enterprise-grade capabilities (OCP Cloud Spec 2.0, SR-IOV, up to 512 name spaces for ZNS support, flexible data placement, NVMe-MI 1.2, advanced security, telemetry, power loss protection) not available on other off-the-shelf controllers – or on any previous Western Digital controllers.
The Ultrastar DC SN861 SSD offers sequential read speeds up to 13.7 GB/s as well as sequential write speeds up to 7.5 GB/s. As for random performance, it boasts with an up to 3.3 million random 4K read IOPS and up to 0.8 million random 4K write IOPS. The drives are available in capacities between 1.6 TB and 7.68 TB with one or three drive writes per day (DWPD) over five years rating as well as in U.2 and E1.S form-factors.
While the two form factors of the SN861 share a similar technical design, Western Digital has tailored each version for distinct workloads: the E1.S supports FDP and performance enhancements specifically for cloud environments. By contrast, the U.2 model is geared towards high-performance enterprise tasks and emerging applications like AI.
Without any doubts, Western Digital's Ultrastar DC SN861 is a feature-rich high-performance enterprise-grade SSD. It has another distinctive feature: a 5W idle power consumption, which is rather low by the standards of enterprise-grade drives (e.g., it is 1W lower compared to the SN840). While the difference with predecessors may be just 1W, hyperscalers deploy thousands of drives and for their TCO every watt counts.
Western Digital's Ultrastar DC SN861 SSDs are now available for purchase to select customers (such as Meta) and to interested parties. Prices are unknown, but they will depend on such factors as volumes.
Sources: Fadu, Storage Review
Storage
Lorem Ipsum is simply dummy text of the printing and typesetting industry. Lorem Ipsum has been the industry's.
In addition to revealing its roadmap and plans concerning its current leading-edge process technologies, TSMC also shared progress of its N2 node as part of its Symposiums 2024. The company's first 2nm-class fabrication node, and predominantly featuring gate-all-around transistors, according to TSMC N2 has almost achieved its target performance and yield goals, which places it on track to enter high-volume manufacturing in the second half of 2025.
TSMC states that 'N2 development is well on track and N2P is next.' In particular, gate-all-around nanosheet devices currently achieve over 90% of their expected performance, whereas yields of 256 Mb SRAM (32 MB) devices already exceeds 80%, depending on the batch. All of this for a node that is over a year away from mass production.
Meanwhile, average yield of a 256 Mb SRAM was around 70% as of March, 2024, up from around 35% in April, 2023. Device performance has also been improving with higher frequencies being achieved while keeping power consumption in check.
Chip designer interest towards TSMC's first 2nm-class gate-all-around nanosheet transistor-based technology is significant, too. The number of new tape-outs (NTOs) in the first year of N2 is over two-times higher than it was for N5. Though with that said, given TSMC's close working relationship with a handful of high-volume vendors – most notably Appe – NTOs can be a very misleading figure since the first year of a new node at TSMC is capacity constrained, and consequently the bulk of that capacity goes to TSMC's priority partners.
Meanwhile, there were considerably more N5 tapeouts in its second year (some where N5P, of course) and N2 promises to have 2.6X more NTOs in its second year. So the node indeed looks quite promising. In fact, based on TSMC's slides (which we're unfortunately not able to republish), N2 is more popular than N3 in terms of NTOs both in the first and the second years of existence.
When it comes to the second year of N2, in the second half of 2026 TSMC plans to roll out its N2P technology, which promises additional performance and power benefits. N2P is expected to improve frequency by 15% - 20%, reduce power consumption by 30% - 40%, and increase chip density by over 1.15 times compared to N3E, significant benefits to move to all-new GAA nanosheet transistors.
Finally, for those companies that need the best in performance, power, and density, TSMC is poised to offer their A16 process in 2026. That node will also bring in backside power delivery, which will add costs, but is expected to greatly improve performance efficiency and scaling.
Semiconductors
Samsung had quietly launched its BM1743 enterprise QLC SSD last month with a hefty 61.44 TB SKU. At FMS 2024, the company had the even larger 122.88 TB version of that SSD on display, alongside a few recorded benchmarking sessions. Compared to the previous generation, the BM1743 comes with a 4.1x improvement in I/O performance, improvement in data retention, and a 45% improvement in power efficiency for sequential writes.
The 128 TB-class QLC SSD boasts of sequential read speeds of 7.5 GBps and write speeds of 3 GBps. Random reads come in at 1.6 M IOPS, while 16 KB random writes clock in at 45K IOPS. Based on the quoted random write access granularity, it appears that Samsung is using a 16 KB indirection unit (IU) to optimize flash management. This is similar to the strategy adopted by Solidigm with IUs larger than 4K in their high-capacity SSDs.
A recorded benchmark session on the company's PM9D3a 8-channel Gen 5 SSD was also on display.
The SSD family is being promoted as a mainstream option for datacenters, and boasts of sequential reads up to 12 GBps and writes up to 6.8 GBps. Random reads clock in at 2 M IOPS, and random writes at 400 K IOPS.
Available in multiple form-factors up to 32 TB (M.2 tops out at 2 TB), the drive's firmware includes optional support for flexible data placement (FDP) to help address the write amplification aspect.
The PM1753 is the current enterprise SSD flagship in Samsung's lineup. With support for 16 NAND channels and capacities up to 32 TB, this U.2 / E3.S SSD has advertised sequential read and write speeds of 14.8 GBps and 11 GBps respectively. Random reads and writes for 4 KB accesses are listed at 3.4 M and 600 K IOPS.
Samsung claims a 1.7x performance improvement and a 1.7x power efficiency improvement over the previous generation (PM1743), making this TLC SSD suitable for AI servers.
The 9th Gen. V-NAND wafer was also available for viewing, though photography was prohibited. Mass production of this flash memory began in April 2024.
Storage




 for servers, as well as an updated LPCAMM standard to go with next-generation LPDDR6 memory.</p>
<p>Just last week <a href="https://www.anandtech.com/show/21470/micron-mrdimm-lineup-expands-datacenter-dram-portfolio">Micron introduced the industry's first DDR5 MRDIMMs</a>, which are timed to launch alongside Intel's Xeon 6 server platforms. But while Intel and its partners are moving full steam ahead on MRDIMMs, the MRDIMM specification has not been fully ratified by JEDEC itself. All told, it's not unusual to see Intel pushing the envelope here on new memory technologies (the company is big enough to bootstrap its own ecosystem). But as MRDIMMs are ultimately meant to be more than just a tool for Intel, a proper industry standard is still needed – even if that takes a bit longer.</p>
<p>Under the hood, MRDIMMs continue to use DDR5 components, form-factor, pinout, SPD, power management ICs (PMICs), and thermal sensors. The major change with the technology is the introduction of multiplexing, which combines multiple data signals over a single channel. The MRDIMM standard also adds RCD/DB logic in a bid to boost performance, increase capacity of memory modules up to 256 GB (for now), shrink latencies, and reduce power consumption of high-end memory subsystems. And, perhaps key to MRDIMM adoption, the standard is being implemented as a backwards-compatible extension to traditional DDR5 RDIMMs, meaning that MRDIMM-capable servers can use either RDIMMs or MRDIMMs, depending on how the operator opts to configure the system.</p>
<p>The MRDIMM standard aims to double the peak bandwidth to 12.8 Gbps, increasing pin speed and supporting more than two ranks. Additionally, a "Tall MRDIMM" form factor is in the works (and pictured above), which is designed to allow for higher capacity DIMMs by providing more area for laying down memory chips. Currently, ultra high capacity DIMMs require using expensive, multi-layer DRAM packages that use through-silicon vias (3DS packaging) to attach the individual DRAM dies; a Tall MRDIMM, on the other hand, can just use a larger number of commodity DRAM chips. Overall, the Tall MRDIMM form factor enables twice the number of DRAM single-die packages on the DIMM.</p>
<p>Meanwhile, this week's announcement from JEDEC offers the first significant insight into what to expect from LPDDR6 CAMMs. And despite LPDDR5 CAMMs having barely made it out the door, some significant shifts with LPDDR6 itself means that JEDEC will need to make some major changes to the CAMM standard to accommodate the newer memory type.</p>
<p align="center"><a href="https://www.anandtech.com/show/21487/jedec-plans-lpddr6-camm-ddr5-mrdimm-specifications"><img alt="" src="https://images.anandtech.com/doci/21487/LPDDR6_LPCAMM.png" style="width: 100%;" /></a><br />
<small><em>JEDEC Presentation: <a href="https://www.jedec.org/sites/default/files/Tom_Schnell_FINAL_%202024-05-03.pdf">The CAMM2 Journey and Future Potential</a></em></small></p>
<p>Besides the higher memory clockspeeds allowed by LPDDR6 – JEDEC is targeting data transfer rates of 14.4 GT/s and higher – the new memory form-factor will also incorporate an altogether new connector array. This is to accommodate LPDDR6's wider memory bus, which sees the channel width of an individual memory chip grow from 16-bits wide to 24-bits wide. As a result, the current LPCAMM design, which is intended to match the PC standard of a cumulative 128-bit (16x8) design needs to be reconfigured to match LPDDR6's alterations.</p>
<p>Ultimately, JEDEC is targeting a 24-bit subhannel/48-bit channel design, which will result in a 192-bit wide LPCAMM. While the LPCAMM connector itself is set to grow from 14 rows of pins to possibly as high as 20. New memory technologies typically require new DIMMs to begin with, so it's important to clarify that this is not unexpected, but at th... Memory)
 for servers, as well as an updated LPCAMM standard to go with next-generation LPDDR6 memory.</p>
<p>Just last week <a href="https://www.anandtech.com/show/21470/micron-mrdimm-lineup-expands-datacenter-dram-portfolio">Micron introduced the industry's first DDR5 MRDIMMs</a>, which are timed to launch alongside Intel's Xeon 6 server platforms. But while Intel and its partners are moving full steam ahead on MRDIMMs, the MRDIMM specification has not been fully ratified by JEDEC itself. All told, it's not unusual to see Intel pushing the envelope here on new memory technologies (the company is big enough to bootstrap its own ecosystem). But as MRDIMMs are ultimately meant to be more than just a tool for Intel, a proper industry standard is still needed – even if that takes a bit longer.</p>
<p>Under the hood, MRDIMMs continue to use DDR5 components, form-factor, pinout, SPD, power management ICs (PMICs), and thermal sensors. The major change with the technology is the introduction of multiplexing, which combines multiple data signals over a single channel. The MRDIMM standard also adds RCD/DB logic in a bid to boost performance, increase capacity of memory modules up to 256 GB (for now), shrink latencies, and reduce power consumption of high-end memory subsystems. And, perhaps key to MRDIMM adoption, the standard is being implemented as a backwards-compatible extension to traditional DDR5 RDIMMs, meaning that MRDIMM-capable servers can use either RDIMMs or MRDIMMs, depending on how the operator opts to configure the system.</p>
<p>The MRDIMM standard aims to double the peak bandwidth to 12.8 Gbps, increasing pin speed and supporting more than two ranks. Additionally, a "Tall MRDIMM" form factor is in the works (and pictured above), which is designed to allow for higher capacity DIMMs by providing more area for laying down memory chips. Currently, ultra high capacity DIMMs require using expensive, multi-layer DRAM packages that use through-silicon vias (3DS packaging) to attach the individual DRAM dies; a Tall MRDIMM, on the other hand, can just use a larger number of commodity DRAM chips. Overall, the Tall MRDIMM form factor enables twice the number of DRAM single-die packages on the DIMM.</p>
<p>Meanwhile, this week's announcement from JEDEC offers the first significant insight into what to expect from LPDDR6 CAMMs. And despite LPDDR5 CAMMs having barely made it out the door, some significant shifts with LPDDR6 itself means that JEDEC will need to make some major changes to the CAMM standard to accommodate the newer memory type.</p>
<p align="center"><a href="https://www.anandtech.com/show/21487/jedec-plans-lpddr6-camm-ddr5-mrdimm-specifications"><img alt="" src="https://images.anandtech.com/doci/21487/LPDDR6_LPCAMM.png" style="width: 100%;" /></a><br />
<small><em>JEDEC Presentation: <a href="https://www.jedec.org/sites/default/files/Tom_Schnell_FINAL_%202024-05-03.pdf">The CAMM2 Journey and Future Potential</a></em></small></p>
<p>Besides the higher memory clockspeeds allowed by LPDDR6 – JEDEC is targeting data transfer rates of 14.4 GT/s and higher – the new memory form-factor will also incorporate an altogether new connector array. This is to accommodate LPDDR6's wider memory bus, which sees the channel width of an individual memory chip grow from 16-bits wide to 24-bits wide. As a result, the current LPCAMM design, which is intended to match the PC standard of a cumulative 128-bit (16x8) design needs to be reconfigured to match LPDDR6's alterations.</p>
<p>Ultimately, JEDEC is targeting a 24-bit subhannel/48-bit channel design, which will result in a 192-bit wide LPCAMM. While the LPCAMM connector itself is set to grow from 14 rows of pins to possibly as high as 20. New memory technologies typically require new DIMMs to begin with, so it's important to clarify that this is not unexpected, but at th... Memory | https://compbuddey.blogspot.com/2024/08/jedec-plans-lpddr6-based-camm-ddr5_5.html)
 for servers, as well as an updated LPCAMM standard to go with next-generation LPDDR6 memory.</p>
<p>Just last week <a href="https://www.anandtech.com/show/21470/micron-mrdimm-lineup-expands-datacenter-dram-portfolio">Micron introduced the industry's first DDR5 MRDIMMs</a>, which are timed to launch alongside Intel's Xeon 6 server platforms. But while Intel and its partners are moving full steam ahead on MRDIMMs, the MRDIMM specification has not been fully ratified by JEDEC itself. All told, it's not unusual to see Intel pushing the envelope here on new memory technologies (the company is big enough to bootstrap its own ecosystem). But as MRDIMMs are ultimately meant to be more than just a tool for Intel, a proper industry standard is still needed – even if that takes a bit longer.</p>
<p>Under the hood, MRDIMMs continue to use DDR5 components, form-factor, pinout, SPD, power management ICs (PMICs), and thermal sensors. The major change with the technology is the introduction of multiplexing, which combines multiple data signals over a single channel. The MRDIMM standard also adds RCD/DB logic in a bid to boost performance, increase capacity of memory modules up to 256 GB (for now), shrink latencies, and reduce power consumption of high-end memory subsystems. And, perhaps key to MRDIMM adoption, the standard is being implemented as a backwards-compatible extension to traditional DDR5 RDIMMs, meaning that MRDIMM-capable servers can use either RDIMMs or MRDIMMs, depending on how the operator opts to configure the system.</p>
<p>The MRDIMM standard aims to double the peak bandwidth to 12.8 Gbps, increasing pin speed and supporting more than two ranks. Additionally, a "Tall MRDIMM" form factor is in the works (and pictured above), which is designed to allow for higher capacity DIMMs by providing more area for laying down memory chips. Currently, ultra high capacity DIMMs require using expensive, multi-layer DRAM packages that use through-silicon vias (3DS packaging) to attach the individual DRAM dies; a Tall MRDIMM, on the other hand, can just use a larger number of commodity DRAM chips. Overall, the Tall MRDIMM form factor enables twice the number of DRAM single-die packages on the DIMM.</p>
<p>Meanwhile, this week's announcement from JEDEC offers the first significant insight into what to expect from LPDDR6 CAMMs. And despite LPDDR5 CAMMs having barely made it out the door, some significant shifts with LPDDR6 itself means that JEDEC will need to make some major changes to the CAMM standard to accommodate the newer memory type.</p>
<p align="center"><a href="https://www.anandtech.com/show/21487/jedec-plans-lpddr6-camm-ddr5-mrdimm-specifications"><img alt="" src="https://images.anandtech.com/doci/21487/LPDDR6_LPCAMM.png" style="width: 100%;" /></a><br />
<small><em>JEDEC Presentation: <a href="https://www.jedec.org/sites/default/files/Tom_Schnell_FINAL_%202024-05-03.pdf">The CAMM2 Journey and Future Potential</a></em></small></p>
<p>Besides the higher memory clockspeeds allowed by LPDDR6 – JEDEC is targeting data transfer rates of 14.4 GT/s and higher – the new memory form-factor will also incorporate an altogether new connector array. This is to accommodate LPDDR6's wider memory bus, which sees the channel width of an individual memory chip grow from 16-bits wide to 24-bits wide. As a result, the current LPCAMM design, which is intended to match the PC standard of a cumulative 128-bit (16x8) design needs to be reconfigured to match LPDDR6's alterations.</p>
<p>Ultimately, JEDEC is targeting a 24-bit subhannel/48-bit channel design, which will result in a 192-bit wide LPCAMM. While the LPCAMM connector itself is set to grow from 14 rows of pins to possibly as high as 20. New memory technologies typically require new DIMMs to begin with, so it's important to clarify that this is not unexpected, but at th... Memory&body=https://compbuddey.blogspot.com/2024/08/jedec-plans-lpddr6-based-camm-ddr5_5.html)


0 Comments