
Samsung has successfully validated its new LPDDR5X-10700 memory with MediaTek's upcoming Dimensity platform. At present, 10.7 GT/s is the highest performing speed grade of LPDDR5X DRAM slated to be released this year, so the upcoming Dimensity 9400 system-on-chip will get the highest memory bandwidth available for a mobile application processor.
The verification process involved Samsung's 16 GB LPDDR5X package and MediaTek's soon-to-be-announced Dimensity 9400 SoC for high-end 5G smartphones. Usage of LPDDR5X-10700 provides a memory bandwidth of 85.6 GB/second over a 64-bit interface, which will be available for bandwidth-hungry applications like graphics and generative AI.
"Working together with Samsung Electronics has made it possible for MediaTek's next-generation Dimensity chipset to become the world's first to be validated at LPDDR5X operating speeds up to 10.7Gbps, enabling upcoming devices to deliver AI functionality and mobile performance at a level we have never seen before," said JC Hsu, Corporate Senior Vice President at MediaTek. "This updated architecture will make it easier for developers and users to leverage more AI capabilities and take advantage of more features with less impact on battery life."
Samsung's LPDDR5X 10.7 GT/s memory in made on the company's 12nm-class DRAM process technology and is said to provide a more than 25% improvement in power efficiency over previous-generation LPDDR5X, in addition to extra performance. This will positively affect improved user experience, including enhanced on-device AI capabilities, such as faster voice-to-text conversion, and better quality graphics.
Overall, the two companies completed this process in just three months. Though it remains to be seen when smartphones based on the Dimensity 9400 application processor and LPDDR5X memory are set to be available on the market, as MediaTek has not yet even formally announced the SoC itself.
"Through our strategic cooperation with MediaTek, Samsung has verified the industry's fastest LPDDR5X DRAM that is poised to lead the AI smartphone market," said YongCheol Bae, Executive Vice President of Memory Product Planning at Samsung Electronics. "Samsung will continue to innovate through active collaboration with customers and provide optimum solutions for the on-device AI era."
Memory

In addition to revealing its roadmap and plans concerning its current leading-edge process technologies, TSMC also shared progress of its N2 node as part of its Symposiums 2024. The company's first 2nm-class fabrication node, and predominantly featuring gate-all-around transistors, according to TSMC N2 has almost achieved its target performance and yield goals, which places it on track to enter high-volume manufacturing in the second half of 2025.
TSMC states that 'N2 development is well on track and N2P is next.' In particular, gate-all-around nanosheet devices currently achieve over 90% of their expected performance, whereas yields of 256 Mb SRAM (32 MB) devices already exceeds 80%, depending on the batch. All of this for a node that is over a year away from mass production.
Meanwhile, average yield of a 256 Mb SRAM was around 70% as of March, 2024, up from around 35% in April, 2023. Device performance has also been improving with higher frequencies being achieved while keeping power consumption in check.
Chip designer interest towards TSMC's first 2nm-class gate-all-around nanosheet transistor-based technology is significant, too. The number of new tape-outs (NTOs) in the first year of N2 is over two-times higher than it was for N5. Though with that said, given TSMC's close working relationship with a handful of high-volume vendors – most notably Appe – NTOs can be a very misleading figure since the first year of a new node at TSMC is capacity constrained, and consequently the bulk of that capacity goes to TSMC's priority partners.
Meanwhile, there were considerably more N5 tapeouts in its second year (some where N5P, of course) and N2 promises to have 2.6X more NTOs in its second year. So the node indeed looks quite promising. In fact, based on TSMC's slides (which we're unfortunately not able to republish), N2 is more popular than N3 in terms of NTOs both in the first and the second years of existence.
When it comes to the second year of N2, in the second half of 2026 TSMC plans to roll out its N2P technology, which promises additional performance and power benefits. N2P is expected to improve frequency by 15% - 20%, reduce power consumption by 30% - 40%, and increase chip density by over 1.15 times compared to N3E, significant benefits to move to all-new GAA nanosheet transistors.
Finally, for those companies that need the best in performance, power, and density, TSMC is poised to offer their A16 process in 2026. That node will also bring in backside power delivery, which will add costs, but is expected to greatly improve performance efficiency and scaling.
Semiconductors
Following a relative lull in the desktop memory industry in the previous decade, the past few years have seen a flurry of new memory standards and form factors enter development. Joining the traditional DIMM/SO-DIMM form factors, we've seen the introduction of space-efficient DDR5 CAMM2s, their LPDDR5-based counterpart the LPCAMM2, and the high-clockspeed optimized CUDIMM. But JEDEC, the industry organization behind these efforts, is not done there. In a press release sent out at the start of the week, the group announced that it is working on standards for DDR5 Multiplexed Rank DIMMs (MRDIMM) for servers, as well as an updated LPCAMM standard to go with next-generation LPDDR6 memory.
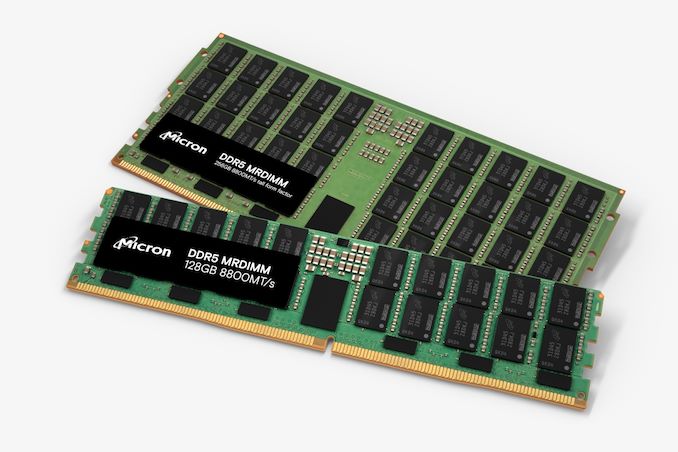
Just last week Micron introduced the industry's first DDR5 MRDIMMs, which are timed to launch alongside Intel's Xeon 6 server platforms. But while Intel and its partners are moving full steam ahead on MRDIMMs, the MRDIMM specification has not been fully ratified by JEDEC itself. All told, it's not unusual to see Intel pushing the envelope here on new memory technologies (the company is big enough to bootstrap its own ecosystem). But as MRDIMMs are ultimately meant to be more than just a tool for Intel, a proper industry standard is still needed – even if that takes a bit longer.
Under the hood, MRDIMMs continue to use DDR5 components, form-factor, pinout, SPD, power management ICs (PMICs), and thermal sensors. The major change with the technology is the introduction of multiplexing, which combines multiple data signals over a single channel. The MRDIMM standard also adds RCD/DB logic in a bid to boost performance, increase capacity of memory modules up to 256 GB (for now), shrink latencies, and reduce power consumption of high-end memory subsystems. And, perhaps key to MRDIMM adoption, the standard is being implemented as a backwards-compatible extension to traditional DDR5 RDIMMs, meaning that MRDIMM-capable servers can use either RDIMMs or MRDIMMs, depending on how the operator opts to configure the system.
The MRDIMM standard aims to double the peak bandwidth to 12.8 Gbps, increasing pin speed and supporting more than two ranks. Additionally, a "Tall MRDIMM" form factor is in the works (and pictured above), which is designed to allow for higher capacity DIMMs by providing more area for laying down memory chips. Currently, ultra high capacity DIMMs require using expensive, multi-layer DRAM packages that use through-silicon vias (3DS packaging) to attach the individual DRAM dies; a Tall MRDIMM, on the other hand, can just use a larger number of commodity DRAM chips. Overall, the Tall MRDIMM form factor enables twice the number of DRAM single-die packages on the DIMM.
Meanwhile, this week's announcement from JEDEC offers the first significant insight into what to expect from LPDDR6 CAMMs. And despite LPDDR5 CAMMs having barely made it out the door, some significant shifts with LPDDR6 itself means that JEDEC will need to make some major changes to the CAMM standard to accommodate the newer memory type.
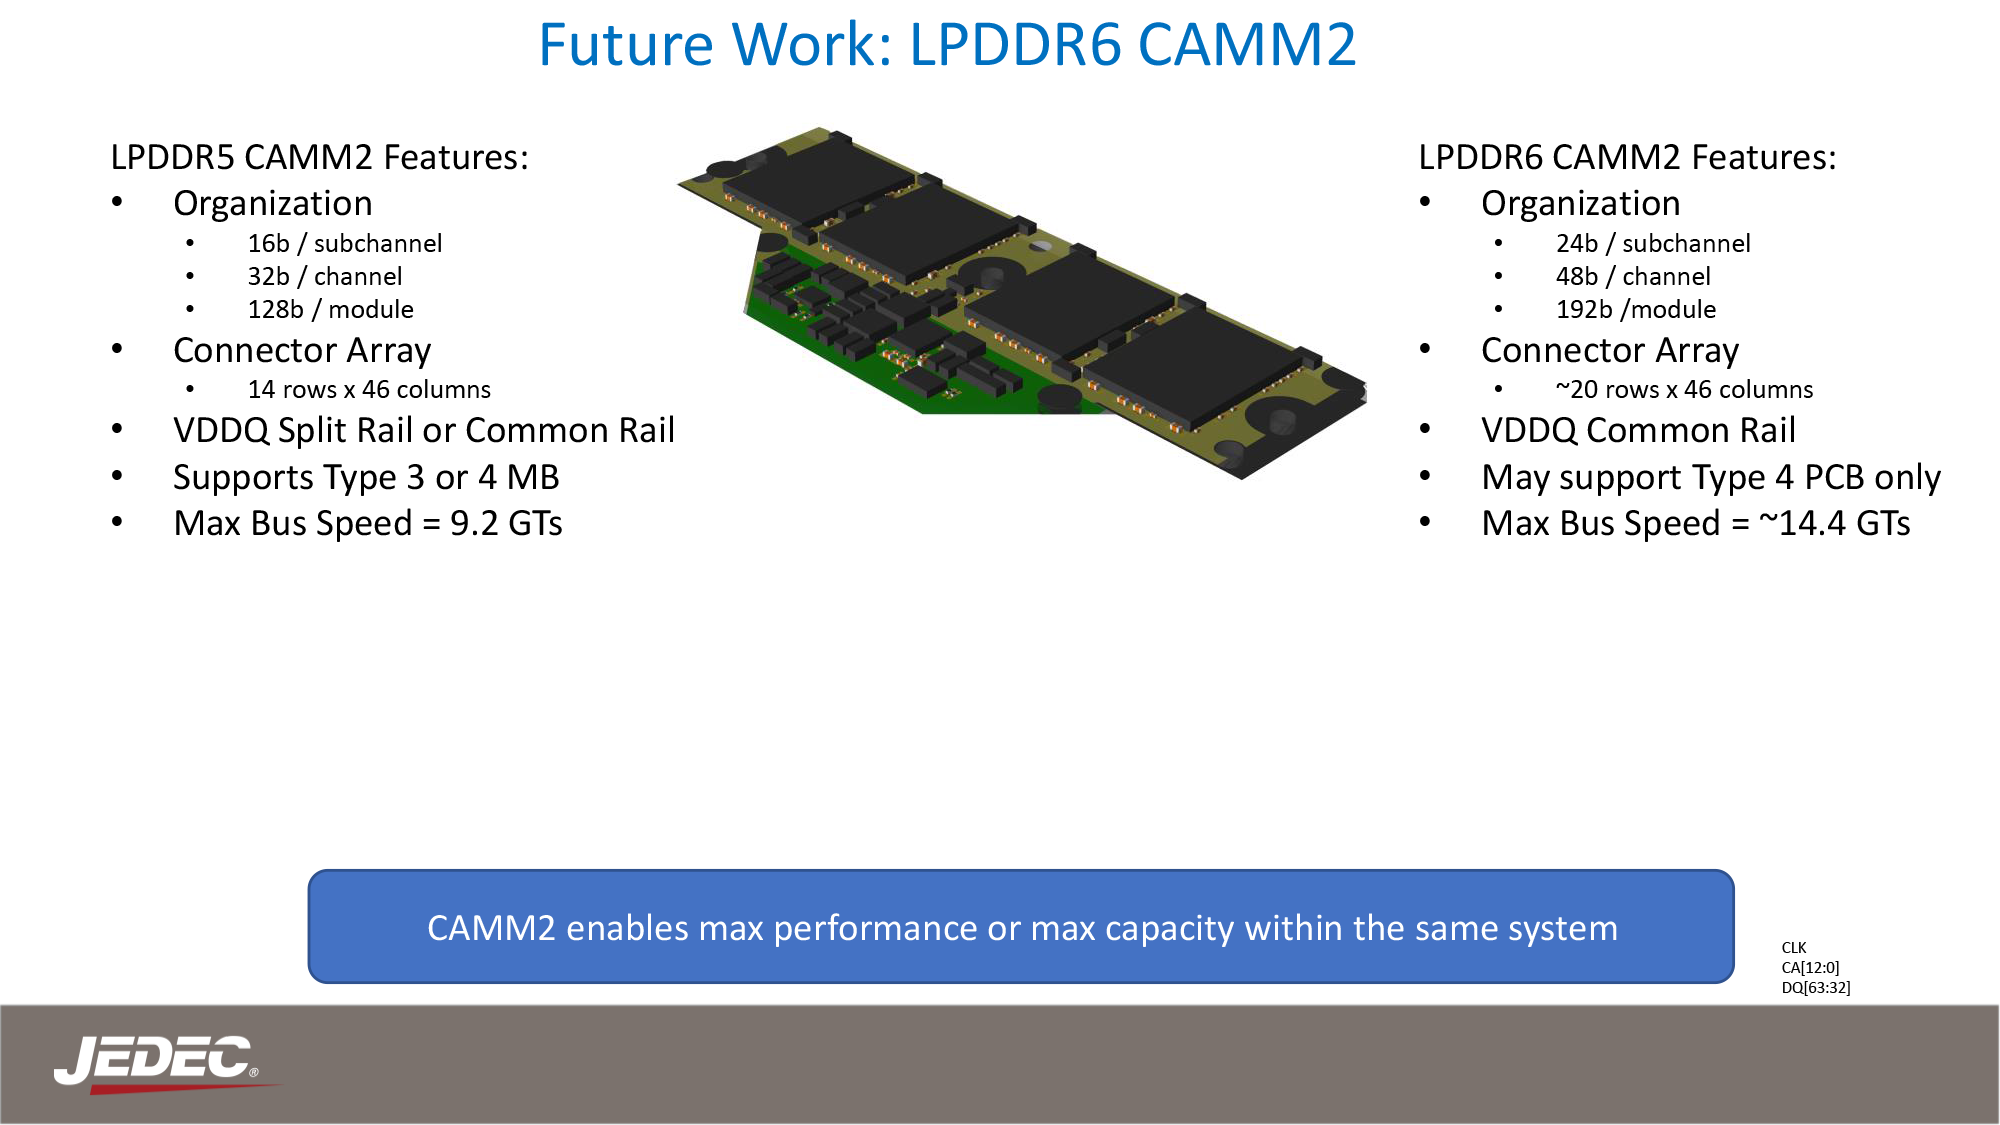
JEDEC Presentation: The CAMM2 Journey and Future Potential
Besides the higher memory clockspeeds allowed by LPDDR6 – JEDEC is targeting data transfer rates of 14.4 GT/s and higher – the new memory form-factor will also incorporate an altogether new connector array. This is to accommodate LPDDR6's wider memory bus, which sees the channel width of an individual memory chip grow from 16-bits wide to 24-bits wide. As a result, the current LPCAMM design, which is intended to match the PC standard of a cumulative 128-bit (16x8) design needs to be reconfigured to match LPDDR6's alterations.
Ultimately, JEDEC is targeting a 24-bit subhannel/48-bit channel design, which will result in a 192-bit wide LPCAMM. While the LPCAMM connector itself is set to grow from 14 rows of pins to possibly as high as 20. New memory technologies typically require new DIMMs to begin with, so it's important to clarify that this is not unexpected, but at th... Memory

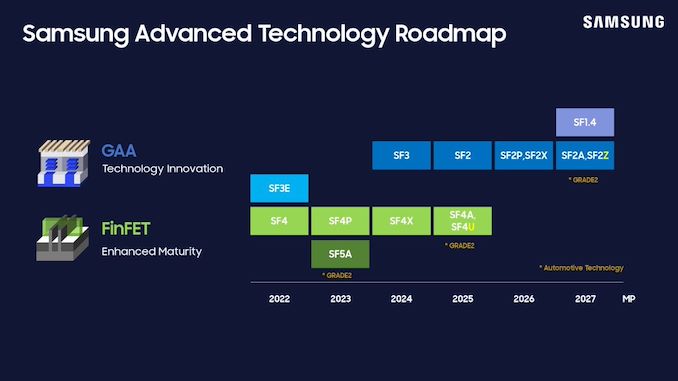
Samsung this week has unveiled its latest process technologies roadmap at the company's Samsung Foundry Forum (SFF) U.S. The new plan covers the evolution of Samsung's 2nm-class production nodes through 2027, including a process technology with a backside power delivery, re-emphasizing plans to bring out a 1.4nm-class node in 2027, and the introduction of a 'high value' 4nm-class manufacturing tech.
Samsung Foundry's key announcements for today are clearly focused on the its 2nm-class process technologies, which are set to enter production in 2025 and will span to 2027, when the company's 1.4-nm class production node is set to enter the scene. Samsung is also adding (or rather, renaming) another 2nm-class node to their roadmap with SF2, which was previously disclosed by Samsung as SF3P and aimed at high-performance devices.
"We have refined and improved the SF3P, resulting in what we now refer to as SF2," a Samsung spokesperson told AnandTech. "This enhanced node incorporates various process design improvements, delivering notable power, performance, and area (PPA) benefits."
| Samsung Foundry for Leading-Edge Nodes Announced on June 12, 2024 Compiled by AnandTech |
||||||||
| HVM Start | 2023 | 2024 | 2025 | 2026 | 2027 | 2027 | ||
| Process | SF3E | SF3 | SF2 (aka SF3P) |
SF2P/SF2X | SF2Z | SF1.4 | ||
| FET | GAAFET | |||||||
| Power Delivery | Frontside | Backside (BSPDN) | ? | |||||
| EUV | 0.33 NA EUV | ? | ? | ? | ? | |||
This is another example of a rebranding of leading-edge fabrication nodes in the recent years by a major chipmaker. Samsung Foundry is not disclosing any specific PPA improvements SF3P has over SF2, and for now is only stating in high-level terms that it will be a better-performing node than the planned SF3P.
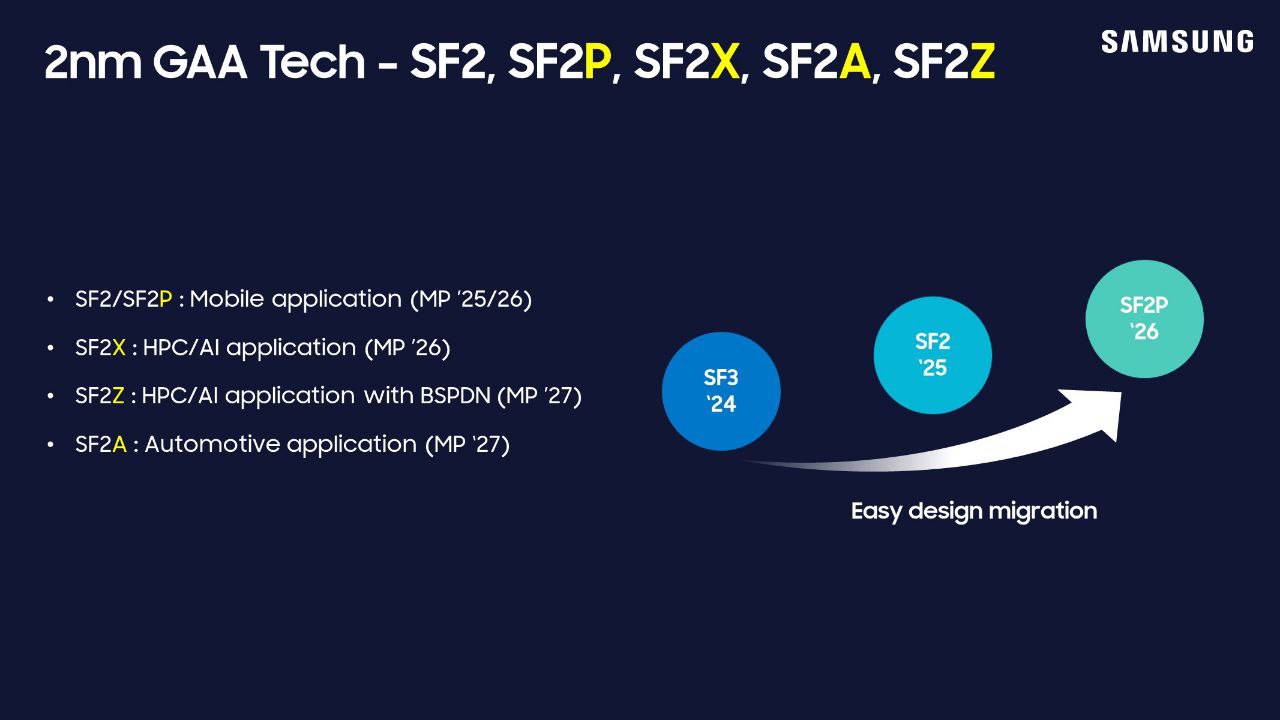
Meanwhile, this week's announcement also includes new information on Samsung's next batch of process nodes, which are planned for 2026 and 2027. In 2026 Samsung will have SF2P, a further refinement of SF2 which incorporates 'faster' yet less dense transistors. That will be followed up in 2027 with SF2Z, which adds backside power delivery to the mix for better and higher quality power delivery. In particular, Samsung is targetting voltate drop (aka IR drop) here, which is an ongoing concern in chip design.
Finally, SF1.4, a 1.4nm-class node, is on track for 2027 as well. Interestingly, however, it looks like it does not feature a backside power delivery. Which, per current roadmaps, would have Samsung as the only foundry not using BSPDN for their first 1.4nm/14Å-class node.
"We have optimized BSPDN and incorporated it for the first time in the SF2Z node we announced today," the spokesperso... Semiconductors

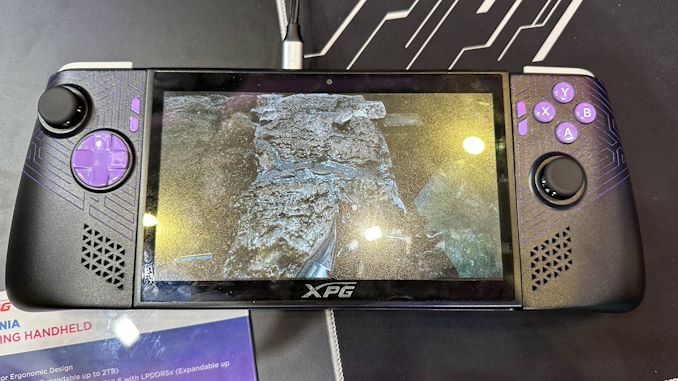
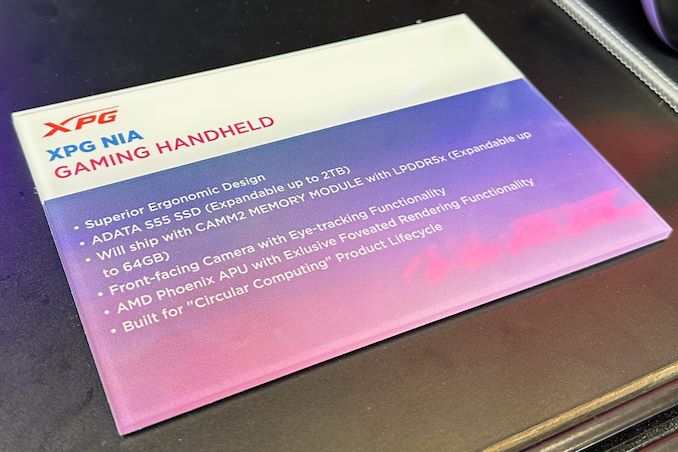
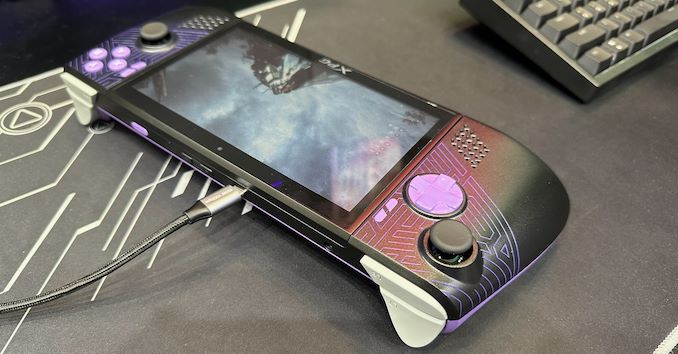
With the rise of the handheld gaming PC market, we've seen PC vendors and their partners toy with a number of tricks and tweaks to improve improve framerates in games, with some of their latest efforts on display at this year's Computex trade show. Perhaps the most interesting find thus far comes from ADATA sub-brand XPG, who is demoing their prototype "Nia" handheld PC, which uses eye tracking and dynamic foveated rendering to further improve their rendering performance.
For those unfamiliar, dynamic foveated rendering is a graphics technique that is sometimes used to boost performance in virtual reality (VR) and augmented reality (AR) applications by taking advantage of how human vision works. Typically, humans can only perceive detailed imagery in the relatively small central area of our vision called the fovea, while our peripheral vision is much less detailed. Dynamic foveated rendering, in turn, exploits this by using real-time eye tracking to determine where the user is looking, and then rendering just that area in high/full resolution, while rendering the peripheral areas in lower resolution. The net result is that only a fraction of the screen is rendered at full detail, which cuts down on the total amount of rendering work required and boosting framerates on performance-limited devices.
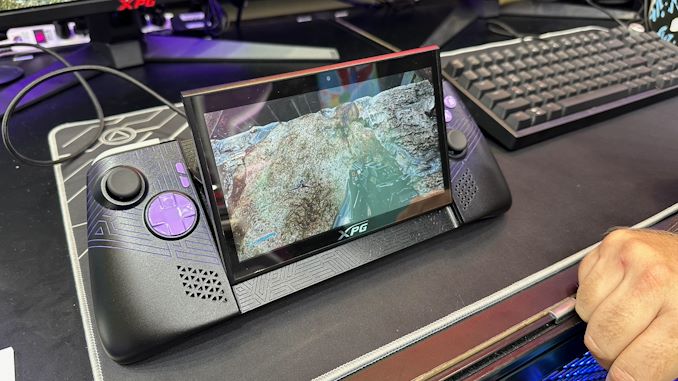
As stated before, this technology is sometimes used in high-end AR/VR headsets, where high resolution displays are placed mere inches from one's face. This ends up being an ideal use case for the technique, since at those distances, only a small fraction of the screen is within the fovea.
Using dynamic foveated rendering for a handheld, on the other hand, is a more novel application. All of the same visual principles apply, but the resolutions at play are lower, and the screen is farther from the users' eyes. This makes a handheld device a less ideal use case, at least on paper, as a larger portion of the screen is going to be in the fovea, and thus will need to be rendered at full resolution. None the less, it will be interesting to see how XPG's efforts pan out, and if dynamic foveated rendering is beneficial enough for handheld PCs. As we sometimes see with trade show demos, not everything makes it out of the prototype stage.
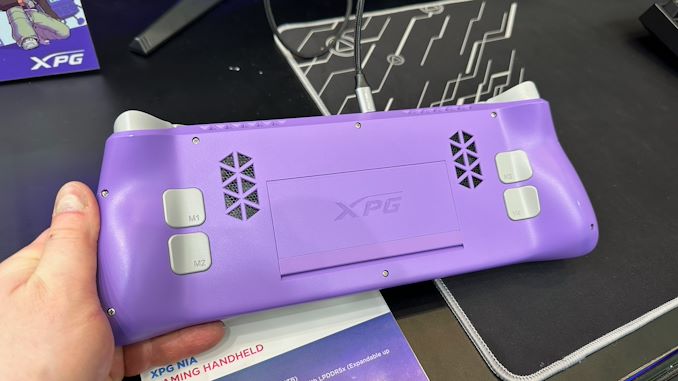
According to a press release put out by ADATA ahead of the trade show, the eye tracking technology is being provided by AMD collaborator Eyeware. Notably, their software-based approach runs on top of standard webcams, rather than requiring IR cameras. So the camera hardware itself should be pretty straight-forward.
Foveated rendering aside, XPG is making sure that the Nia won't be a one-trick pony. The handheld's other major claim to fame is its hardware swappability. The prototype handheld not only features a removable M.2-2230 SSD, but the company is also taking advantage of the recently-introduced LPCAMM2 memory module standard to introduce removable DRAM. Via a hatch in the back of the handheld, device owners would be able to swap out LPCAMM2 LPDDR5X modules for higher capacity versions. This would give the handheld an additional degree of future-proofness over current handhelds, which use non-replaceable soldered-down memory.
Rounding out the package, the current prototype is based on an AMD's Zen 4 Phoenix APU, which is used across both of the company's current mobile lines (Ryzen Mobile 7000/8000 and Ryzen Z1). Meanwhile, the unit's display is adjustable, allowing it to be angled away from the body of the handheld.
Assuming all goes well with the prototype, XPG aims to release a finished product in 2025.

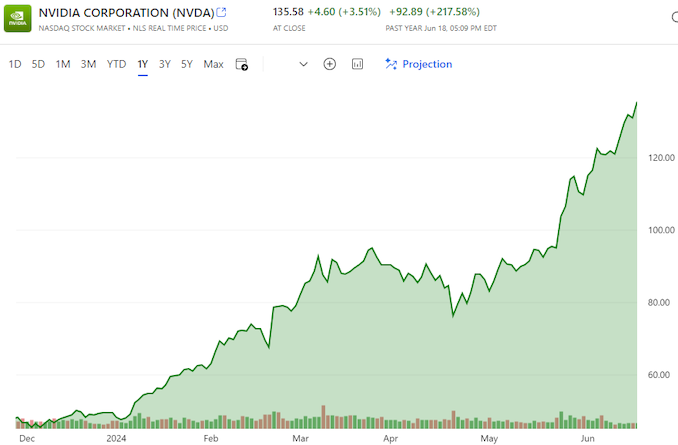
Thanks to the success of the burgeoning market for AI accelerators, NVIDIA has been on a tear this year. And the only place that’s even more apparent than the company’s rapidly growing revenues is in the company’s stock price and market capitalization. After breaking into the top 5 most valuable companies only earlier this year, NVIDIA has reached the apex of Wall Street, closing out today as the world’s most valuable company.
With a closing price of $135.58 on a day that saw NVIDIA’s stock pop up another 3.5%, NVIDIA has topped both Microsoft and Apple in valuation, reaching a market capitalization of $3.335 trillion. This follows a rapid rise in the company’s stock price, which has increased by 47% in the last month alone – particularly on the back of NVIDIA’s most recent estimates-beating earnings report – as well as a recent 10-for-1 stock split. And looking at the company’s performance over a longer time period, NVIDIA’s stock jumped a staggering 218% over the last year, or a mere 3,474% over the last 5 years.
NVIDIA’s ascension continues a trend over the last several years of tech companies all holding the top spots in the market capitalization rankings. Though this is the first time in quite a while that the traditional tech leaders of Apple and Microsoft have been pushed aside.
| Market Capitalization Rankings | ||
| Market Cap | Stock Price | |
| NVIDIA | $3.335T | $135.58 |
| Microsoft | $3.317T | $446.34 |
| Apple | $3.285T | $214.29 |
| Alphabet | $2.170T | $176.45 |
| Amazon | $1.902T | $182.81 |
Driving the rapid growth of NVIDIA and its market capitalization has been demand for AI accelerators from NVIDIA, particularly the company’s server-grade H100, H200, and GH200 accelerators for AI training. As the demand for these products has spiked, NVIDIA has been scaling up accordingly, repeatedly beating market expectations for how many of the accelerators they can ship – and what price they can charge. And despite all that growth, orders for NVIDIA’s high-end accelerators are still backlogged, underscoring how NVIDIA still isn’t meeting the full demands of hyperscalers and other enterprises.
Consequently, NVIDIA’s stock price and market capitalization have been on a tear on the basis of these future expectations. With a price-to-earnings (P/E) ratio of 76.7 – more than twice that of Microsoft or Apple – NVIDIA is priced more like a start-up than a 30-year-old tech company. But then it goes without saying that most 30-year-old tech companies aren’t tripling their revenue in a single year, placing NVIDIA in a rather unique situation at this time.
Like the stock market itself, market capitalizations are highly volatile. And historically speaking, it’s far from guaranteed that NVIDIA will be able to hold the top spot for long, never mind day-to-day fluctuations. NVIDIA, Apple, and Microsoft’s valuations are all within $50 billion (1.%) of each other, so for the moment at least, it’s still a tight race between all three companies. But no matter what happens from here, NVIDIA gets the exceptionally rare claim of having been the most valuable company in the world at some point.
(Carousel image courtesy MSN Money)
GPUs
Lorem Ipsum is simply dummy text of the printing and typesetting industry. Lorem Ipsum has been the industry's.





0 Comments